NLP · Data science project
Tweet Emotion Classification
Reading six emotions in short, messy social media text
- Test accuracy
- 93.47%
- Emotions
- 6
- Tweets
- 416,809
The problem
Sort tweets into sadness, joy, love, anger, fear or surprise. Tweets are short and informal, and some emotions use much the same words: love sounds a lot like joy, and fear a lot like anger. The classes are also uneven, with far more joy and sadness than surprise.
The data
A labeled tweet dataset, included in the repo (text.csv)
416,809 English tweets, each labeled with one of six emotions
Approach
- Cleaned and tokenized the text, built a vocabulary and padded each tweet to a fixed length.
- Compared the words used for each emotion, including word clouds per emotion.
- Trained an embedding layer feeding a bidirectional GRU. More complex networks didn't beat it, so the simpler model stayed.
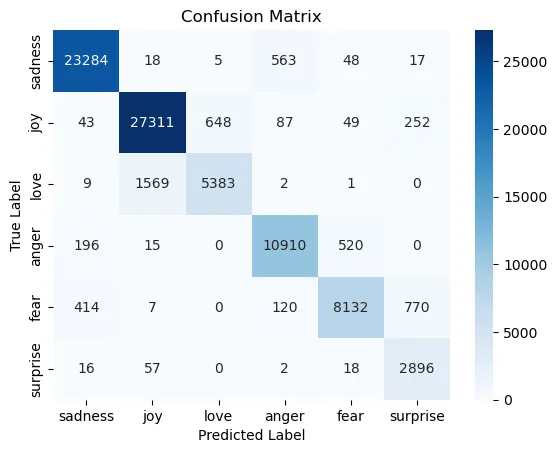
- Tested on held-out tweets and studied the mistakes with a confusion matrix.
Results
The model reached 93.47% accuracy on the test set (test loss 0.1047). Most errors are between similar emotions: 1,569 love tweets were labeled joy, and fear was most often confused with surprise and sadness.
Tools
- Python
- TensorFlow
- Keras
- scikit-learn
- pandas
- NumPy
- seaborn